Deep learning and MLOps workflows
Keep training with the tools built for it, and evaluate inference in QA-Board: what each model does on each input, against the reference model, commit after commit. This page shows how projects connect the two.
Training trackers like Weights & Biases, MLflow or TensorBoard are great at what they're built for (as of 2026): logging experiments without setting up a project, comparing many training curves at once, early stopping, reports. Evaluating a model for release asks other questions, where QA-Board helps:
- Which inputs got worse? Go from a metric to the outputs of one difficult input, side by side with the reference model's, with synced viewers.
- Is it better than the release? Compare with a reference model, or a milestone.
- Did this commit change the results? Integrate with source control and the CI.
- Can someone else try it on new inputs? People run more tests from the web app.
The detector use case shows it on an int8 quantization: the model is 72% smaller, and the metrics per slice and object size show what it loses.
Show each run's model and link to its training
Have run() return the model's details as params: QA-Board shows them on the run's card, as configuration tags,
and badges as links, for instance to the model's card or its training page. The detector does it for each model it
evaluates:
    return {
        **metrics,
        'is_failed': False,
        'params': {
            'model': model_id,
            'badges': [{'text': f"Model card kd-{flags['model_version']}", 'icon': 'id-number',
                        'href': f"https://models.kitefin.example/detector/kd-{flags['model_version']}#{kind}-{size}"}],
        },
    }
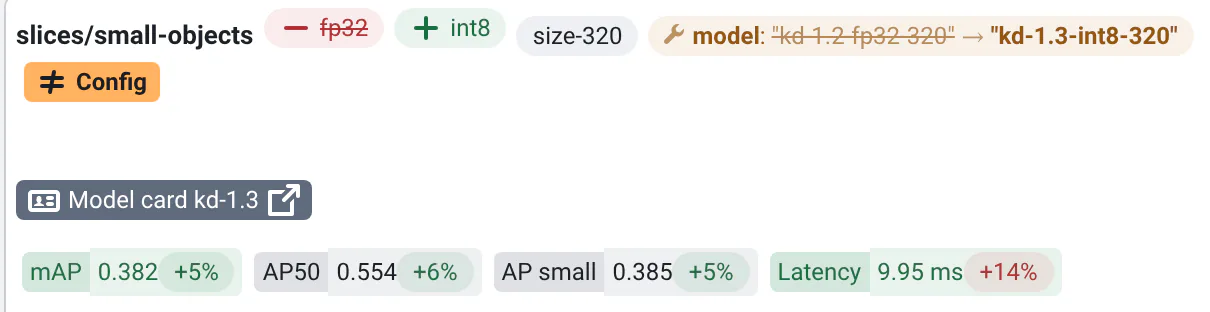
See metrics shown as a run-time configuration for the format. Projects often add the training's hyperparameters and final losses, read from their tracker's API.
Evaluate a model from your training runs
Write a run() function that:
- reads a model id from
context.params, or defaults to the model trained for the commit; - fetches that model and its details from your tracker or model registry: hyperparameters, a link to its training page;
- runs the model on
context.input_path, and saves what you want to look at: detections drawn on the images, a per-class report, precision-recall curves; - computes the evaluation metrics, and returns them with the model's details as
params.
Then evaluate any model on your test set, from a terminal or from the web app, with the model's id as a tuning parameter:
qa --share --label kd-1.4-rc1 --tuning '{"model": "kd-1.4-rc1"}' batch ci
Here model is your own parameter's name, read by your run(). A script that lists your recent training runs can
start an evaluation of the best ones the same way.
Gate model releases in the CI
In an MLOps pipeline, the CI:
- trains a network, or fetches the one trained for the commit;
- fails if the training loss is too high, in your training script;
- runs inference on an evaluation batch with
qa batch; - fails if the evaluation metrics got worse, with
qa gate(experimental). The detector's gate keeps its mAP above a floor and its AP on small objects within 10% of the reference model's:
# Experimental: may change without notice
gate:
  reference: main
  batches: [ci]
  rules:
    - {metric: map, min: 0.15}                       # median over the batch's runs
    - {metric: ap_small, max_regression: 10%}
    - {metric: map, per_test_max_regression: 25%}    # no slice and variant much worse than in the reference
  max_failed_runs: 0
To search the parameters of a model's inference (a score threshold, the quantization settings), see automated tuning.