Running your code
qa runs your code through one Python function that you write: run(context), in qa/main.py. The context says
which input to work on, with which configuration, and where to save the output files. run() returns the metrics.
Write run()
If your code is in Python, import it and call it:
from my_project import process  # your code


def run(context):
    result = process(context.input_path, params=context.params)
    result.image.save(context.output_dir / "out.png")
    return {"psnr": result.psnr, "is_failed": False}
Then run it on one input, with its path relative to your inputs' folder (see Inputs):
qa run --input charts/slanted-edge.png
In the camera ISP example, qa prints where the outputs go, then what the code prints, then the metrics run()
returned:
Outputs: /home/ines/kitefin/camera-isp/output/linux/charts-slanted-edge
K3 camera: charts/slanted-edge.png, 1224x816, ISO 100 (gain 1x)
ISP (linux): hamilton-adams demosaic, bilateral denoise x1.6, sharpen x1.5 (clamp: local-contrast), filmic tone curve
  1 black level, white balance        21 ms
  2 demosaic                          55 ms
  3 denoise                          217 ms
  4 sharpen                           73 ms
  5 tone map                          13 ms
psnr 41.29 | ssim 0.9964 | mtf50 0.293 | overshoot 0.04729 | runtime 0.8864
{'psnr': 41.290915250993336, 'ssim': 0.9963992583219179, 'mtf50': 0.2930029684772476, [...], 'is_failed': False}
The example's qa/main.py is a
complete run() to copy from: it simulates the camera, runs the pipeline, saves the output image and each stage, then
measures PSNR, sharpness and halos.
Results stay on your computer, in output/. To see them in the web app, add
--share: qa --share run --input charts/slanted-edge.png. In CI, qa always
sends them.
What qa does around run()
- It reads qaboard.yaml and imports the file named by
project.entrypoint. That file's folder is on Python's import path, soqa/main.pycan import the modules next to it. - It creates
context.output_dir, empties it, and callsrun(context). - It saves the metrics
run()returns in metrics.json, everything printed in log.txt, and the lists of input and output files in manifest.inputs.json and manifest.outputs.json. - With
--shareor in CI, it sends the metrics to QA-Board, which shows the output files from where they are.
What run() returns is a dict of metrics: the web app shows the numbers, compared with the reference's. See
Metrics for strings, units, and which way is better. A run fails when run()
returns "is_failed": True, raises an exception (qa prints its traceback in the log), or returns something else
than a dict. qa run then exits with 1.
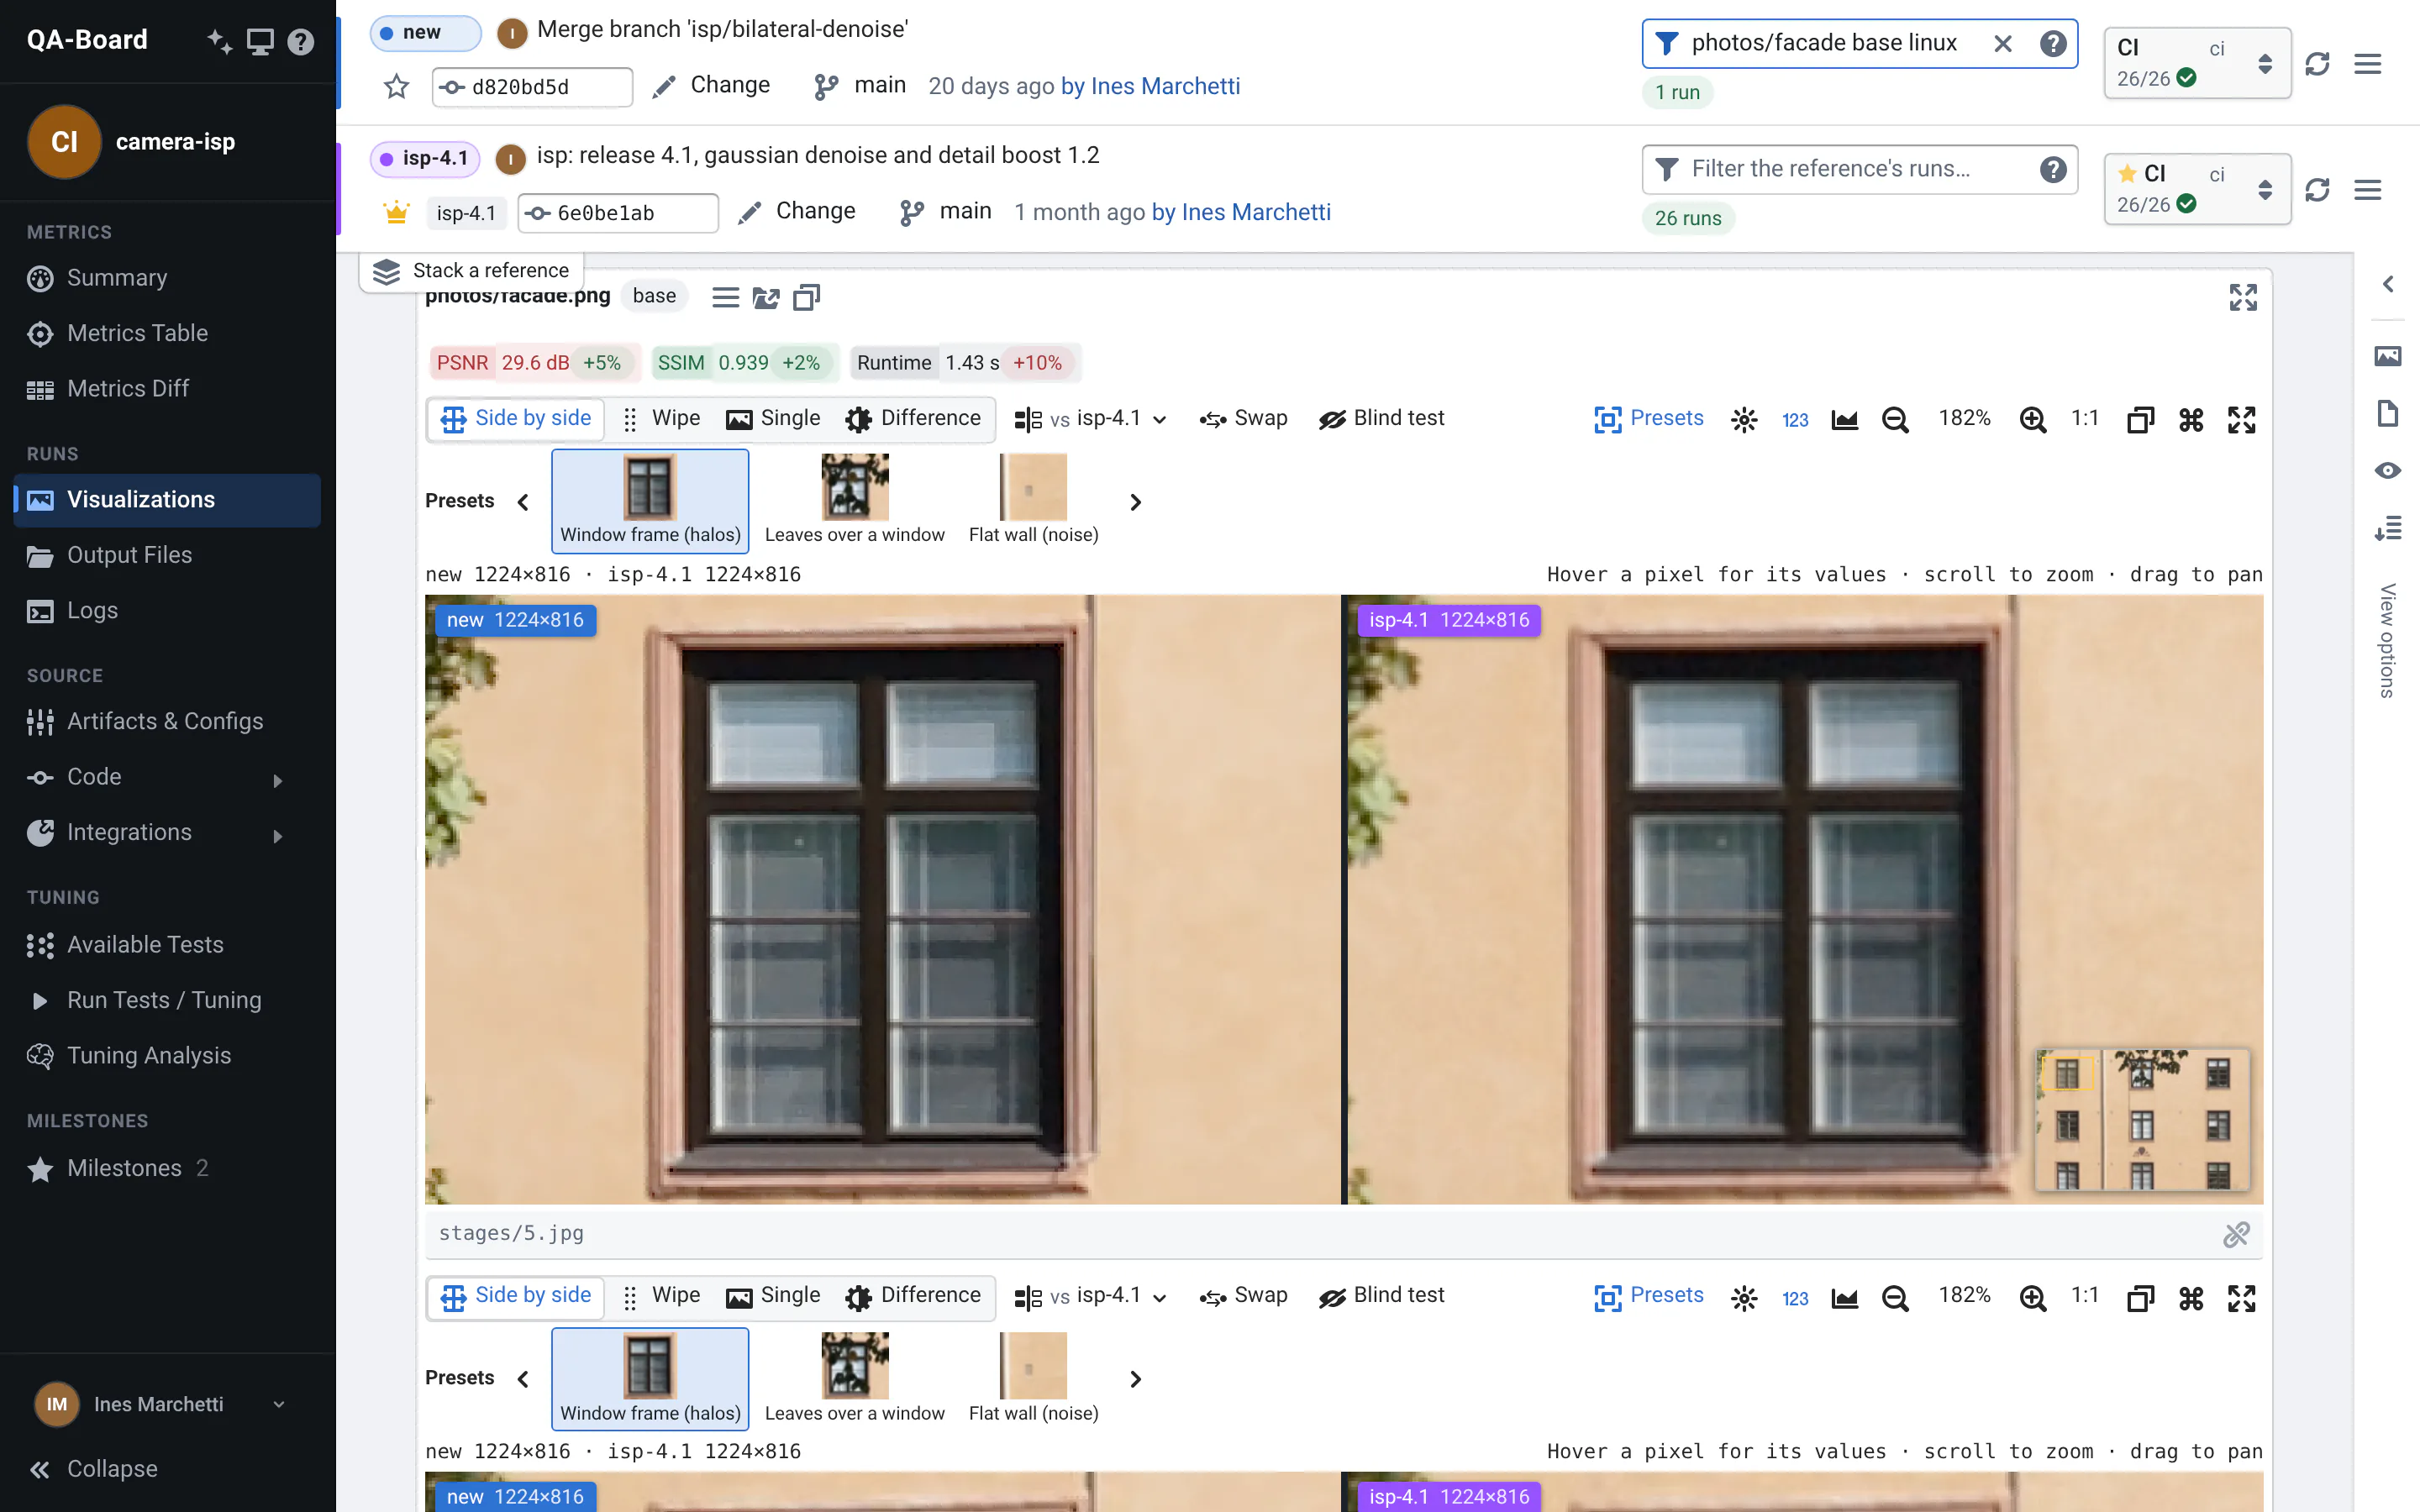
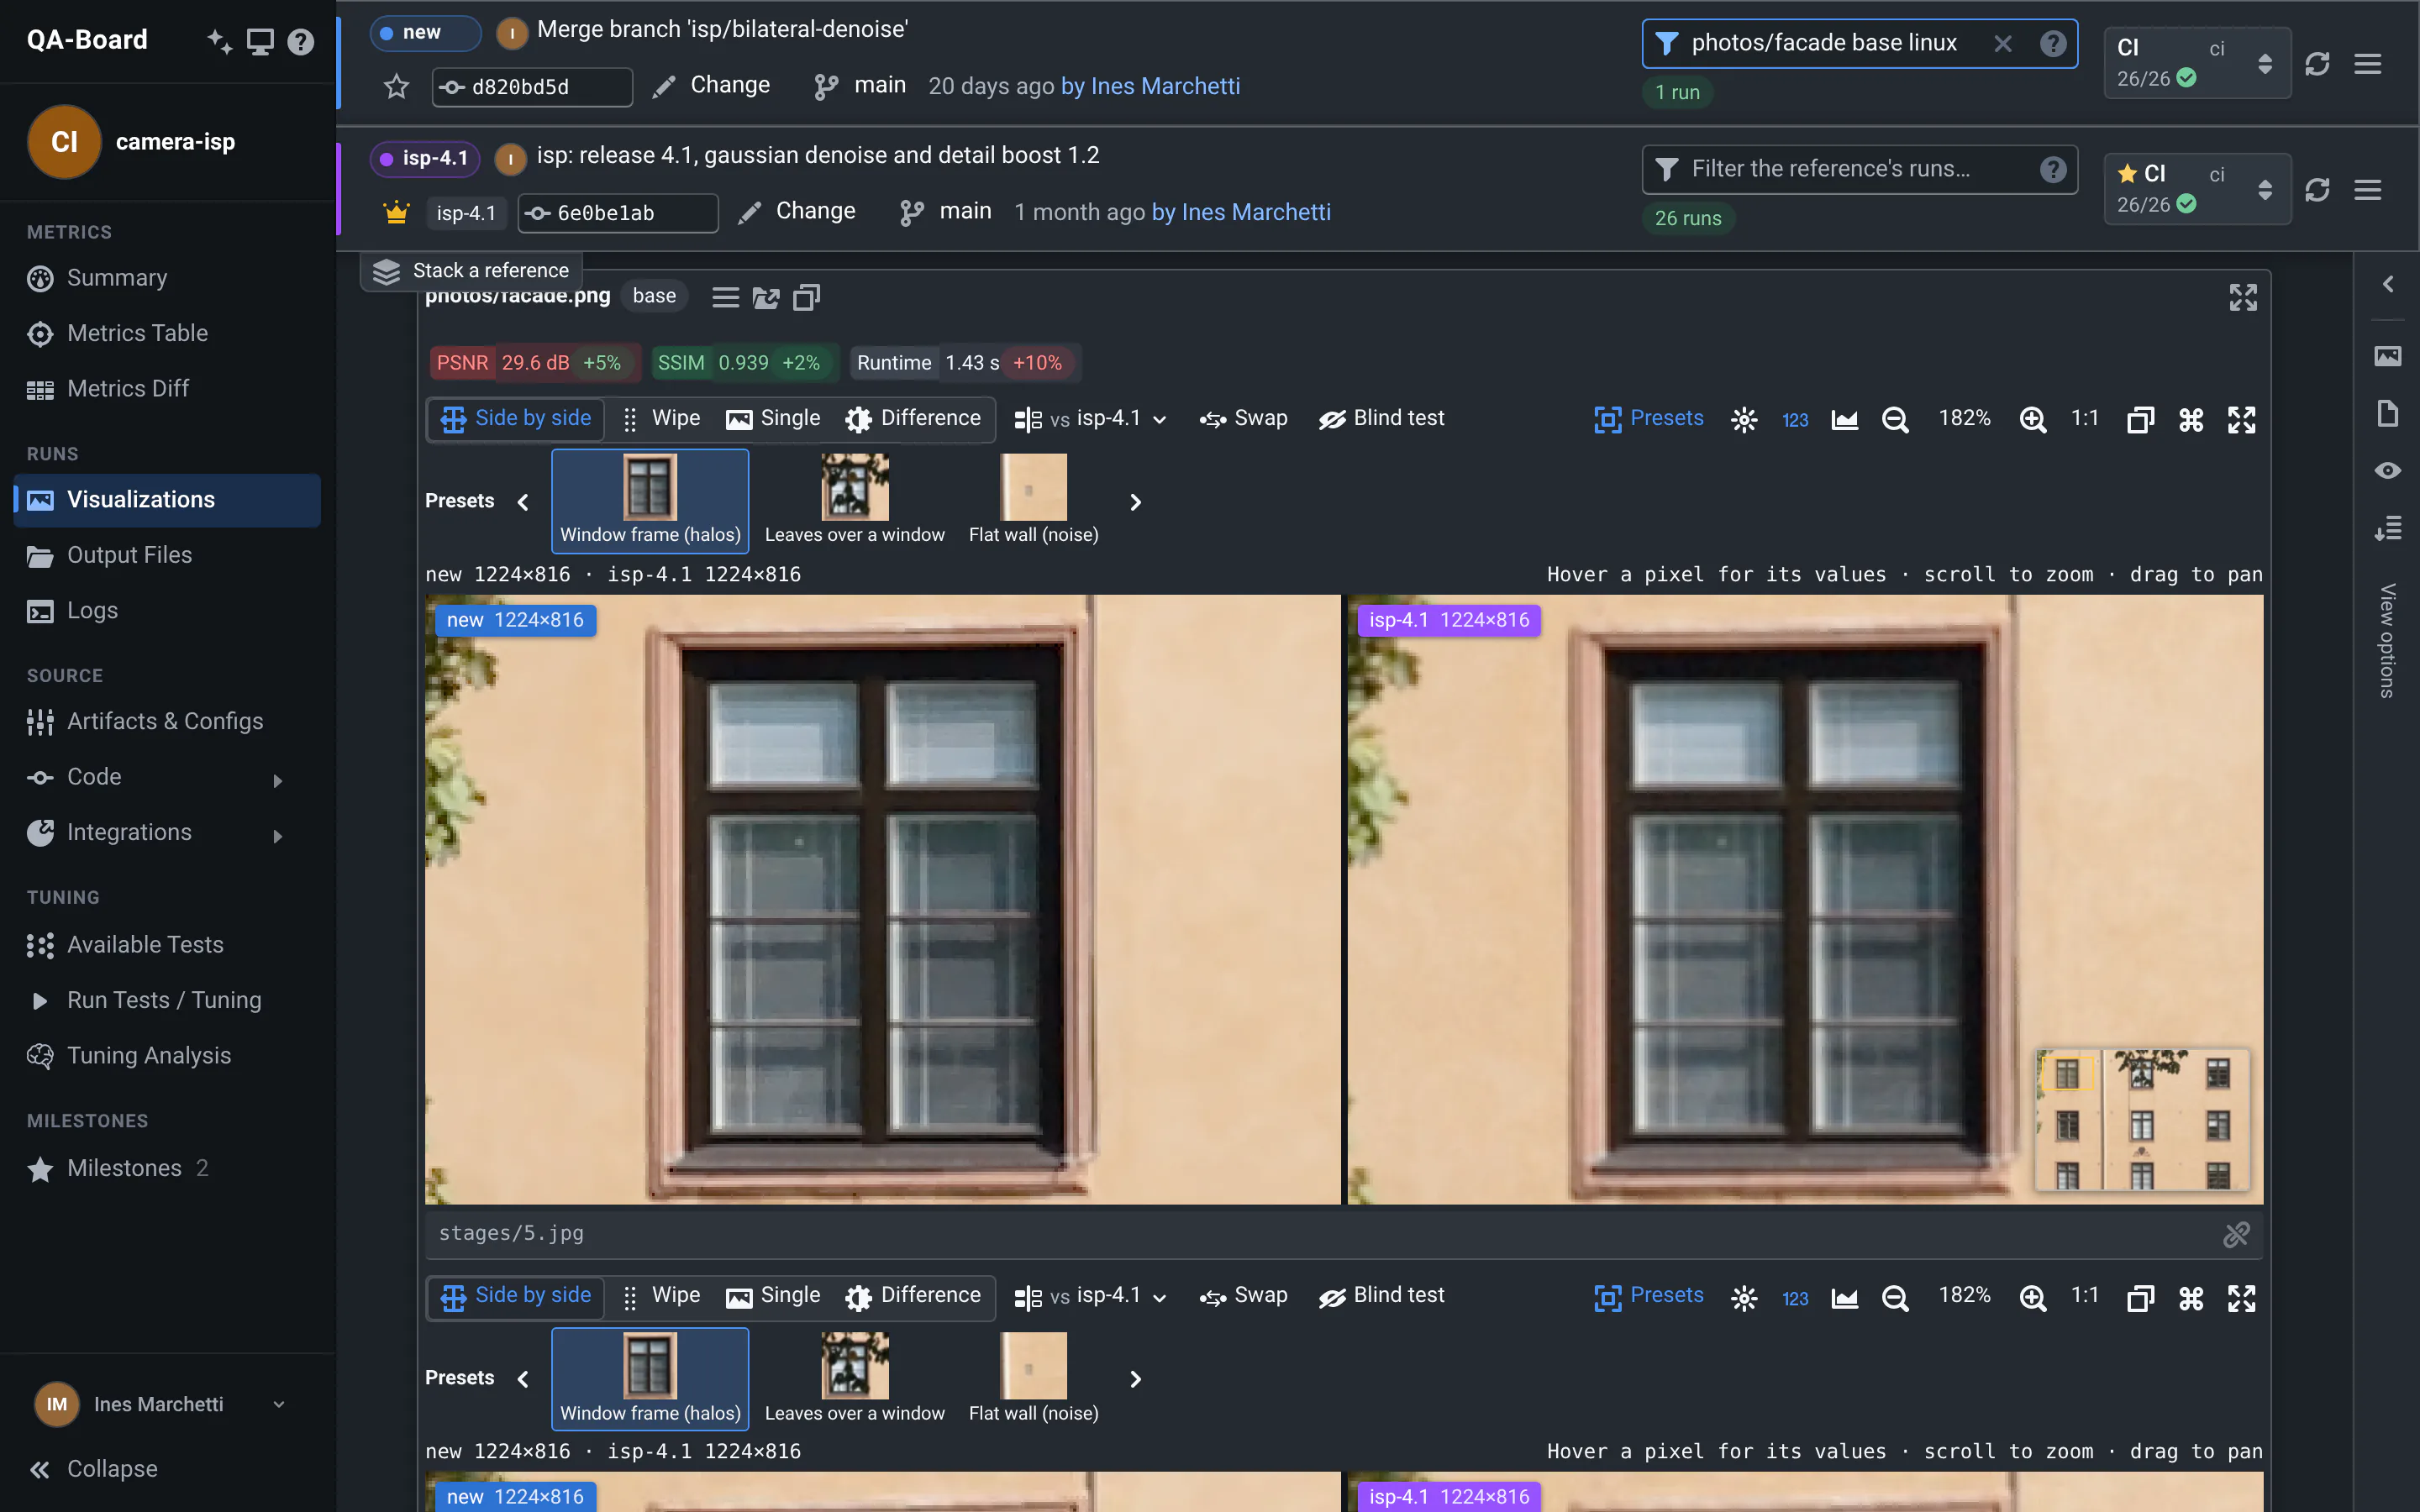
To see the outputs in the web app, list them in qaboard.yaml: see Visualizations.
Run an executable
qa doesn't build your code: build it first, in CI too. Then start it from run(), and read what it wrote:
import json
import subprocess


def run(context):
    process = subprocess.run(
        ["build/my-tool", "--input", str(context.input_path), "--output", str(context.output_dir)],
        stdout=subprocess.PIPE, stderr=subprocess.STDOUT, text=True,
    )
    print(process.stdout)  # saved in the run's log
    if process.returncode != 0:
        return {"is_failed": True}
    metrics = json.loads((context.output_dir / "metrics.json").read_text())
    return {**metrics, "is_failed": False}
qa saves in log.txt what Python prints. An executable that writes to the terminal itself isn't in the log: capture
its output and print it, like above.
To see the log while the executable runs, print its output line by line. The inference gateway example starts its benchmark this way, and fails the run when the benchmark crashes:
    command = [
        str(build.binary()), '--out', str(output_dir), '--seed', str(seed),
        '--repeats', str(settings['repeats']), '--warmup', str(settings['warmup_s']), '--duration', str(settings['duration_s']),
        *gateway_args(flags), *load_args(profile), f"hidden={size['hidden']}", f"top_k={size['top_k']}",
    ]
    env = {**os.environ, 'GATEWAY_ALLOCATOR': flags['allocator'], 'RUST_BACKTRACE': '1'}
    print(f"$ GATEWAY_ALLOCATOR={flags['allocator']} gateway-bench {' '.join(command[3:])}", flush=True)
    process = subprocess.Popen(command, env=env, stdout=subprocess.PIPE, stderr=subprocess.STDOUT, text=True, errors='replace')
    for line in process.stdout:
        print(line, end='', flush=True)
    if process.wait() != 0:
        print(f'gateway-bench exited with {process.returncode}', flush=True)
        return {'is_failed': True}
Arguments after the input are forwarded to your code, as context.forwarded_args. It's handy to try a flag of your
executable:
qa run --input profiles/steady-high.yaml --verbose
#=> context.forwarded_args == ['--verbose']
Compute metrics in a second step
Some projects run their code, then compute metrics from its output files. Put that second step in a postprocess()
function, next to run():
def postprocess(runtime_metrics, context):
    detections = load_detections(context.output_dir / "detections.json")
    return {**runtime_metrics, **evaluate(detections, context.input_path), "is_failed": False}
qa runcallspostprocess()with whatrun()returned, unless the run failed or you give--no-postprocess.qa postprocess --input <input>redoes only the second step, on the files of the previous run.runtime_metricsis then empty, and the metrics of the previous run are kept unlesspostprocess()returns new values.- For a whole batch:
qa batch <batch> --action-on-existing postprocess, see existing results.
Import results computed elsewhere
To compare your code with a benchmark or a reference implementation, import their results as runs. Say they are next to your images, in a folder per input:
<database>
├── images
│  ├── A.jpg
│  └── B.jpg
└── standard-benchmark
   └── images
      ├── A
      │  └── output.jpg
      └── B
         └── output.jpg
Give the benchmark as a configuration, in a batch:
import-standard-benchmark:
  configs:
  - benchmark: standard-benchmark
  inputs:
  - images
When it's set, run() copies the benchmark's files instead of running your code:
import shutil


def run(context):
    benchmark = context.params.get("benchmark")
    if benchmark:
        outputs = context.database / benchmark / context.rel_input_path.with_suffix("")
        shutil.copytree(outputs, context.output_dir, dirs_exist_ok=True)
        return {"is_failed": False}
    # otherwise, run your code, which writes output.jpg
Run qa --share batch import-standard-benchmark, then make that batch a
milestone to compare with it in a click.
Reference
The context
| Property | What it is |
|---|---|
input_path | The input's absolute path. |
rel_input_path, input | The input's path relative to the database, as you give it to qa run --input and in batches: as a Path, and as a string. |
database | The folder with your inputs (absolute), see Inputs. |
type | The input type, see input types. |
input_metadata | The input's metadata, if your entrypoint has a metadata() function: see Metadata. |
configs | The list of configurations, then the tuning parameters. Your code decides what they mean: see Configurations. |
params | The mappings of configs, merged: often all you need. |
platform | linux or windows, or what qa --platform sets, e.g. hw-model. |
forwarded_args | The arguments after the input: qa run --input A.jpg --verbose. |
output_dir | Where to save the output files. qa creates it, and empties it before the run. |
dryrun | True with qa --dryrun run: print what you would do, without doing it. |
id | The run's id in QA-Board. None when results aren't sent: without --share outside CI, with --offline, or when the server can't be reached. |
configurations, extra_parameters | configs in two parts: the configurations, and the tuning parameters with the forwarded arguments. Rarely needed. |
The runs you read back from scripts have the same names (results in scripts).
Environment variables
qasetsQA_LABELto the run's label (fromqa --label), e.g. for your code's own logs.QA_USERoverrides the user nameqauses (by default, the logged-in user), e.g. for{user}in storage locations.GIT_MESSAGEandGIT_AUTHORED_DATETIMEoverride the commit message and date sent to QA-Board, e.g. when your code isn't in a git repository.
qa's settings in your code
Your code can read what qa knows:
from qaboard.config import config, project, commit_id, commit_branch, is_ci
config: the project's qaboard.yaml, merged with the site defaults, as a dict.project: the project's name, as a path, e.g.kitefin/camera-isp.commit_id,commit_branch: the commit and branch being run.is_ci: whetherqaruns in CI (theCIorGIT_COMMITenvironment variable is set).